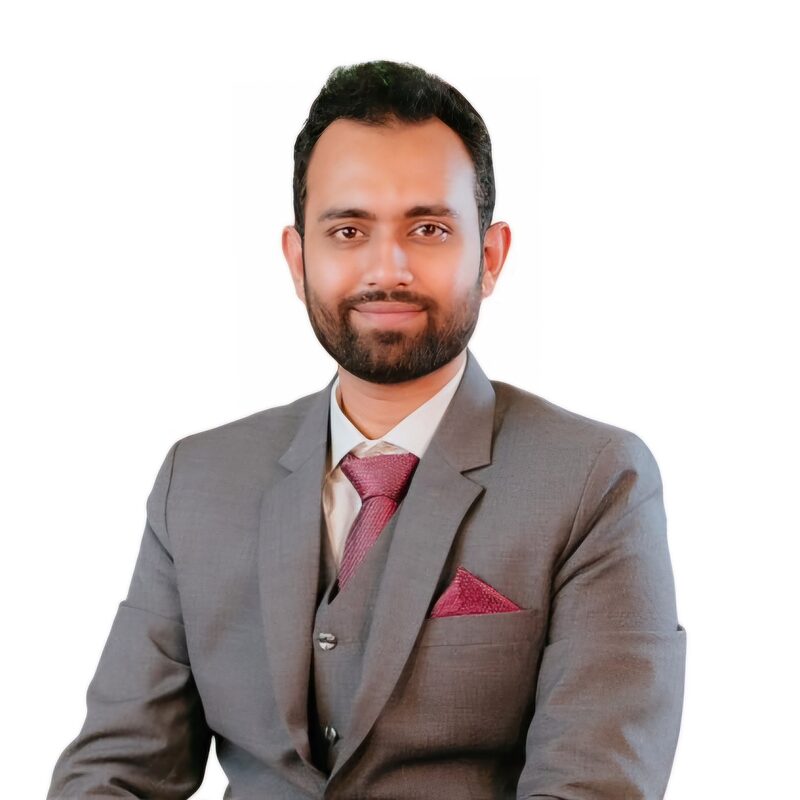
Ashik Mostofa Tonmoy
Independent DevOps & Platform Engineering Consultant

Cloud bills, cut. Kubernetes, shipped.

I help SaaS teams cut cloud spend without losing capacity, ship production-grade GitOps platforms in weeks, and embed as fractional DevOps when a full-time platform hire isn't justified yet.

Book a 30-min intro call →How I workFree, 30 minutes. No pitch deck — we scope the problem or I tell you I'm not the right fit. GMT+6 — overlapping EU mornings and US Pacific evenings.
● Cost
~40%
Off an enterprise SaaS cloud bill, capacity unchanged. Still ~33% below the original baseline as workload grows.
● Scale
1,000+
Apps managed via the GitOps platform I architected, across 10 production K8s clusters.
● Reliability
99.9%
Availability against contracted SLAs, on infrastructure serving 2M+ daily requests.
● Teaching
800+
Engineers trained across 12 cohorts as Lead DevOps Instructor at Ostad.
Services

How teams actually hire me.

Starting points below — the exact number comes out of a call once we've scoped the problem. One to four weeks for fixed projects; monthly billing for retainers.

K8s01 · Platform

Kubernetes & GitOps platform setup

Production-ready Kubernetes + GitOps from scratch — multi-cluster, secure, observable, deployable in weeks not quarters.

  • Cluster architecture & tenancy model
  • ArgoCD, app-of-apps, secrets management
  • CI/CD pipelines & deploy automation
  • SLI/SLO + error budget definition
  • Fault injection before release — pod kill, node loss, net partition
  • Runbooks, ADRs, team handoff
from $6,500 · single cluster, 2–3 weeks
Multi-cluster or multi-environment builds are scoped separately — same architecture, more of it.
Ideal for: Series A–C SaaS scaling past 5 engineers, or teams stuck on legacy infra they're afraid to touch.
40% cloud spend cut →
$02 · Audit

Cloud cost optimization audit

A full audit of what you're spending and why. Where nobody has owned cloud cost, that has meant 40%+ off the bill. Where someone has, it means a written answer you can take to a board — and either way you keep the governance playbook that stops it drifting back.

  • Full account audit — waste, tagging, RIs
  • Rightsizing & spot strategy
  • Reserved / savings plan modeling
  • FinOps governance playbook
  • Implementation support
from $2,500 · fixed scope, 1–2 weeks
If there is nothing meaningful to find, the report says so in writing — and you keep the governance playbook either way.
Ideal for: Companies spending $20K+/month on cloud with no dedicated FinOps owner.
CI03 · Pipelines

CI/CD pipeline engineering

One-click repo-to-production pipelines with security scanning baked in. .NET, Java, Python, JS, Go — all covered.

  • GitHub Actions or GitLab CI design
  • Reusable workflows & templates
  • SonarQube + OWASP Dependency-Track
  • Workload identity & OIDC federation — kill client-ID/secret auth
  • Promote-via-PR release flow
  • Developer-facing docs
from $4,000 · 2–4 weeks, scales with scope
Ideal for: Engineering teams shipping slowly or fighting with brittle legacy Jenkins.
∞04 · Embed

Fractional DevOps & advisory

Embedded senior DevOps expertise without a full-time hire. Architecture reviews, mentoring, hiring help, on-call backup.

  • 8–10 hrs / week, ongoing
  • Architecture & cost reviews
  • PR review & mentoring
  • On-demand crisis response
  • Help hiring your first platform engineer
from $3,500 / month · 8–10 hrs / week
Ideal for: Early-stage startups (pre-DevOps hire) or scaleups bridging to their first dedicated platform engineer.
AI05 · AI infra

AI/ML platform & GPU workload infrastructure

The infrastructure layer under your models — GPU scheduling, training and inference pipelines, and the compliance controls that come with regulated data.

  • GPU/ML workload orchestration on Kubernetes
  • Training & inference pipeline automation
  • Mixed spot/on-demand capacity for cost control
  • HIPAA / regulated-data ML platforms
  • Model deployment lead time: weeks → hours
from $6,500 · scoped like a platform build
Ideal for: ML teams whose data scientists are blocked on infrastructure, or AI products moving from notebook to production.
Book a 30-min intro call →Not sure which? We'll figure it out on the call.
Case studies

Four platforms I owned in production.

Problem → approach → result. Each of these I built and ran as the accountable engineer inside the company operating it, not as a short external drop-in. Clients and absolute figures stay under NDA; happy to walk through any of them on a call.

Enterprise SaaSAzureCloud cost

Cut a SaaS company's cloud bill ~40% — no capacity lost.

Problem
The Azure bill had climbed steadily with no FinOps owner. Engineering was being asked to cut spend without slowing delivery.
Approach
Full account audit. Surfaced untagged waste, oversized VMs, idle services, missing reserved coverage. Modeled the right RI + spot mix. Wrote a governance playbook so savings wouldn't drift back.
Outcome
A ~40% reduction at the time, and still ~33% below the original baseline as workload grows. No capacity cut, no velocity hit. The governance playbook is the team's FinOps reference.
Read the full case study →
Multi-tenant PaaSKubernetesGitOps platform

Built a GitOps platform managing 1,000+ apps from a blank repo.

Problem
Tenant onboarding was manual and slow. Deployments drifted between clusters. Platform team on-call for routine changes that should have been self-service.
Approach
Designed a multi-cluster ArgoCD control plane on the app-of-appsets pattern — one root Application fanning out into per-service, per-cluster Applications. Codified tenant provisioning, split control plane from Helm values across two repos, wrote the handoff docs the platform team operates from.
Outcome
1,000+ apps via GitOps across 10 production clusters. A new service is one declaration plus a values file — minutes, not a ticket. Platform team reclaimed on-call hours.
Read the full case study →
Health-techML on patient dataHIPAA compliance

HIPAA-compliant ML infrastructure that shipped in hours, not weeks.

Problem
ML team needed to deploy patient-data workloads under strict HIPAA controls — without slowing data scientists down or turning platform into a ticket queue.
Approach
Isolated network architecture, encryption-at-rest by default, automated audit logging, developer experience that hid the compliance machinery behind a clean abstraction.
Outcome
Production HIPAA-aligned infra delivered on schedule. Model deployment lead time went from weeks to hours, and the ML team self-serviced deployments without platform intervention. Zero security incidents through my time on the platform, and the move to mixed spot and on-demand capacity cut the bill substantially.
Read the full case study →
Enterprise SaaS · PlatformSelf-managed K8sCloud-agnostic

Built a self-managed RKE2 platform as a cloud-agnostic alternative to AKS.

Problem
The platform was locked to one managed Kubernetes provider. Enterprise clients with data-residency and sovereignty requirements needed the same product running outside a hyperscaler — without a second operating model.
Approach
Security-hardened RKE2 provisioned end-to-end with Ansible. Defense in depth: admin plane behind a VPN and cloud security group, host firewall scoped to peer nodes, WireGuard-encrypted node-to-node traffic because the overlay crosses a public segment. A self-hosted OIDC issuer lets out-of-cloud workloads federate to the managed secret store without static credentials.
Outcome
Deployed across development, staging and production, running on plain VMs alongside the managed AKS estate on the same GitOps control plane and delivery pipeline. Provider lock-in stopped being a commercial blocker.
Read the full case study →
Approach

How the work actually runs.

Outcome-led scopes. Written before built. Async-friendly across time zones. Your team owns it after.

Fixed-scope project

Defined deliverable, timeline, and price. Best when the problem is known and you want a clean line-item on the books.

2 – 4 weeks

Fractional retainer

Embedded with your team. Architecture, mentoring, on-call backup, hiring support. Best when a full-time platform engineer isn't justified yet.

8 – 10 hrs / week

Audit or advisory

A focused audit, a paid strategy call, or a single discrete deliverable. For second opinions, due diligence, or unblocking a decision.

1 – 2 weeks
What you actually receive
  • A written engagement doc before any work starts — scope, success criteria, what is explicitly out.
  • An audit report on audit engagements: findings ranked by annual saving against effort, each with the command or console path to verify it yourself, plus the governance rules that stop it recurring.
  • The infrastructure itself, in your Git — Terraform, Ansible or manifests in your repositories under your review process. Nothing lives on my machine.
  • Runbooks and ADRs for what was built, and a recorded walkthrough with the engineers who will operate it.
  • A weekly written update for the duration — shipped, blocked, next. No status meeting required.
Written before built.

Every engagement starts with a written scope and success criteria. No goalpost drift mid-project.

Async-first across time zones.

I overlap with US, EU and APAC business hours. Loom + written updates beat status meetings.

Outcomes over hours.

Fixed-scope wherever the work allows. Retainers measured in shipped wins, not seat time.

Your team owns it after.

Runbooks, ADRs, walkthroughs, pairing. Nothing I build is a black box you can't operate.

About

I'm Ashik Mostofa Tonmoy — quietly working with serious teams, globally.

Ashik Mostofa Tonmoy

Independent DevOps & Platform Engineering consultant based in Bangladesh, working remote-first with clients across the US, EU and APAC. I architect platforms production teams actually want to operate — Kubernetes done right, GitOps that survives the second year, and cloud bills that match the value being shipped. Full resume (PDF) ↓

Accountable for production infrastructure, not advising on it. Infrastructure I've built serves 2M+ daily requests at 99.9% availability against contracted SLAs. GitOps platforms I've architected manage 1,000+ apps across 10 clusters. HIPAA-compliant systems delivered with zero security incidents, and I've worked under client NDAs across ISO 27001, GDPR, FADP and SOC 2 environments. Outside client work I'm Lead DevOps Instructor at Ostad, where I've trained 800+ engineers across 12 cohorts. B.Sc. Electronics & Communication Engineering, KUET.

Kubernetes & delivery
KubernetesRKE2ArgoCDHelmTektonGitHub ActionsGitLab CI/CD
Cloud & infrastructure as code
AzureAWSTerraformAnsibleWireGuard
Observability
PrometheusGrafanaDatadogOpenTelemetry
Security
SonarQubeTrivyOIDC federation
Languages
PythonGoBash
Experience

Six roles, three of them owning production infrastructure.

Where the case studies came from. I still own production infrastructure day to day — client work runs alongside it, for a small number of teams at a time. Operating other people's estates is how I learned what actually survives the second year.

  1. Aug 2024 — Present

    Senior DevOps Engineer · Selise Digital Platforms

    Infrastructure owner for the company's commercial multi-tenant PaaS, serving enterprise clients across Europe and North America — 10 clusters, 8 environments, 2M+ daily requests at 99.9% availability against contracted SLAs. Built the enterprise Tekton CI/CD system from zero — one-click commit-to-production with SAST/SCA scanning inline — and eliminated client-ID/secret authentication platform-wide with Managed Identity and OIDC federation. Selected for the SELISE LEAP leadership development program.

  2. May 2025 — PresentPart-time

    Lead DevOps Instructor · Ostad

    Designed and deliver “Mastering DevOps” — 17 weeks, 18 modules, 36 live sessions. 800+ engineers trained across 12 cohorts, from university students to senior professionals.

  3. Apr 2024 — Jul 2024

    DevOps Engineer · W3 Engineers Ltd.

    Replaced manual AWS provisioning with Terraform IaC — 75% faster deployments, configuration drift eliminated. Passed an external security audit and migrated 15+ legacy applications with zero-downtime blue-green deploys.

  4. Nov 2023 — Mar 2024Company ceased operations

    DevOps Engineer · Zaynax Group

    Built and operated a highly available on-premises Kubernetes platform on air-gapped infrastructure meeting government compliance requirements. Cut development-to-production cycle time 60% for a team new to DevOps. Deployed Harbor registry with automated image scanning, blocking known-vulnerable images from reaching production.

  5. Jan 2023 — Oct 2023

    MLOps Engineer · InNeed Intelligent Cloud

    Ran AWS EKS with mixed fixed and spot capacity for a HIPAA-compliant ML platform — model deployment lead time down from weeks to hours, zero security incidents, and a substantial cut in infrastructure cost.

  6. Dec 2021 — Dec 2022

    Machine Learning Engineer · ACME AI

    Led the Bill & Melinda Gates Foundation-funded livestock detection project using computer vision, reaching 92% production accuracy, and led an 8-person cross-functional team across data acquisition, training and deployment. Released 4 open-source datasets with 1,000+ downloads.

FAQ

What clients actually ask first.

The 10 questions that come up on every intro call, cleared up in advance.

Do you take freelance and contract work?

Yes — freelance and contract engagements are most of what I do, fully remote for clients in the US, EU and APAC. That covers fixed-scope projects (a cloud cost audit, a Kubernetes or GitOps platform build, a CI/CD pipeline rebuild) and ongoing fractional DevOps retainers. I contract directly and through the usual freelance platforms.

What time zones do you work in?

Based GMT+6 (Bangladesh) but built for async. Overlap with EU mornings, US Pacific evenings, and the full APAC business day. Most clients see me responsive 12+ hours a day on Slack / Linear / email.

You have a full-time role — how does client work fit around it?

Openly: I'm the infrastructure owner for a commercial multi-tenant SaaS platform, and I take a small number of outside engagements alongside it. That is why the experience on this site is current rather than remembered — I'm operating production Kubernetes this week, not describing a platform I left three years ago. In practice it means async delivery, a cap on how much I take on at once, and no scope I can't hold. If an engagement needs more hands or full business-hours coverage, I bring in engineers from a small delivery company I co-founded — you contract with me, and I stay accountable either way.

Do you work fixed-fee or hourly?

Fixed-scope whenever the work allows it — that protects both of us. Retainers are quoted monthly. I don't publish hourly rates because the deliverable is what matters. Pricing is discussed on the intro call once we've scoped the problem.

What if my infrastructure is already well optimised?

Then the audit says so in writing, with the working shown — which is worth having when a board or an investor asks the question. I would rather tell you there is 6% on the table than manufacture a finding to justify the invoice. In practice it is rarely all-or-nothing: teams with disciplined rightsizing often still have no reserved-capacity strategy, or no way to answer "who owns this workload and can we delete it". The governance half of the engagement is what stops an already-efficient estate drifting back over the following year. And if the intro call makes it clear there isn't enough on the table to justify the fee, I'll say so on the call rather than scope it.

How fast can you start?

Audits and advisory sessions usually start within 1–2 weeks of signing and run 1–2 weeks. Larger projects (cluster builds, platform work) typically kick off 2–4 weeks out. If something's on fire, say so on the intro call — I keep a small amount of capacity for urgent work.

Do you work with my existing team or solo?

Both. Most engagements run alongside an internal team — I embed, pair with your engineers, and leave them able to operate what I've built. Where there isn't yet a platform team to pair with, I deliver directly, and for larger builds I pull in engineers from the delivery company I co-founded. Scope isn't capped by one person's calendar.

What does the first 30 days look like?

Week 1: scoping interviews, access, written engagement doc. Week 2: discovery / audit, surfaced findings, prioritised plan. Weeks 3–4: implementation on the agreed scope, weekly written check-ins, live demo at end of week 4.

How do contracts and payment work?

You contract with me personally. I invoice in whatever currency works for you, paid by direct bank transfer or Wise — if you need something else, we'll make it work. Fixed projects usually bill by milestone; otherwise terms are negotiable. Either way the exact terms go into the written engagement doc before any work starts.

Do you sign NDAs?

Yes — happy to sign before the first call. I've worked under client NDAs across ISO 27001, GDPR, FADP and SOC 2 environments.

— Let's talk

Let's see if I'm a fit for what you're actually trying to ship.

A 30-minute call. Tell me the shape of the problem. If I'm the right fit we'll scope an engagement; if I'm not, I'll point you at someone who is.

Currently booking Q4 2026
tonmoy.ashik@gmail.com →

Want a reference first? Ask on the call and I'll put you in touch with someone I've delivered for, before we agree on anything.

Or send a brief

No spam · reply within 24h on business days

What you send goes to my inbox and nowhere else — no CRM, no mailing list, no ad tracking. Privacy.